By Alexander Jordan, Founder
Published: October 1, 2026 | Updated: October 21, 2026
Every post in this series closes the same way: book a call and we run the AI Perception Report on your brand before we ever speak. That sentence asks a founder to give up thirty minutes for something they cannot picture. It could be a two-page PDF assembled in a hurry. It could be a sales call wearing a diagnostic costume.
So here is the whole thing, slide by slide, including what it does not cover. The example is a real report we ran on Floyd (floydhome.com). Floyd is not a client of ours, so the name stays in.
What does the report actually show?
Five slides. No pricing, no packages, no methodology pitch.
The leaderboard. Your competitors are scored by the Competitor Scorecard on AI-search presence, content depth, SEO maturity and brand clarity, with one line each on why the model prefers them. Your row is on that list. Floyd came fourth of four, behind IKEA, Lovesac and Burrow, and trails on all four scores. The models send modular furniture buyers to IKEA, Lovesac and Burrow first, and the widest gap is AI-search presence: 40 points behind IKEA.

What AI thinks you are. Four engines, ChatGPT, Claude, Gemini and Perplexity, queried by LLM Perception in fresh sessions with no history and web search off (on for Gemini, which can't turn it off), so what comes back is what the models learned rather than what they can look up, with Gemini the one exception. You get three scores out of 100, Recognition, Accuracy and Positioning, broken out per engine, and a list of what the models currently get wrong about you.
Floyd scored 49 on Recognition, 54 on Accuracy and 36 on Positioning. ChatGPT and Gemini know Floyd as a modular furniture brand. Claude and Perplexity don't recognise it at all. On the errors list, ChatGPT names dining tables as a flagship Floyd category, which overstates it, because Floyd's best-known piece is the bed. Gemini says Floyd makes desks, but Floyd's standing desk is discontinued, so that answer is out of date, not invented.
The slide also carries a purchase-intent line: brand appears in 8 of 12, the right product appears in 3 of 12. Being mentioned is not being bought.

The answer you have, and the answer you want. The exact paragraph a model gives about you today, quoted in full, next to the exact paragraph we would want it to give. Both written out, no summarising. This is the cheapest slide in the report to produce and the one most often quoted back to us. For Floyd, ChatGPT's answer today never mentions Detroit, The Floyd Bed or any named product. The answer we wrote does, and it also names the modular sectionals, The Block storage system and The Floyd Leg.

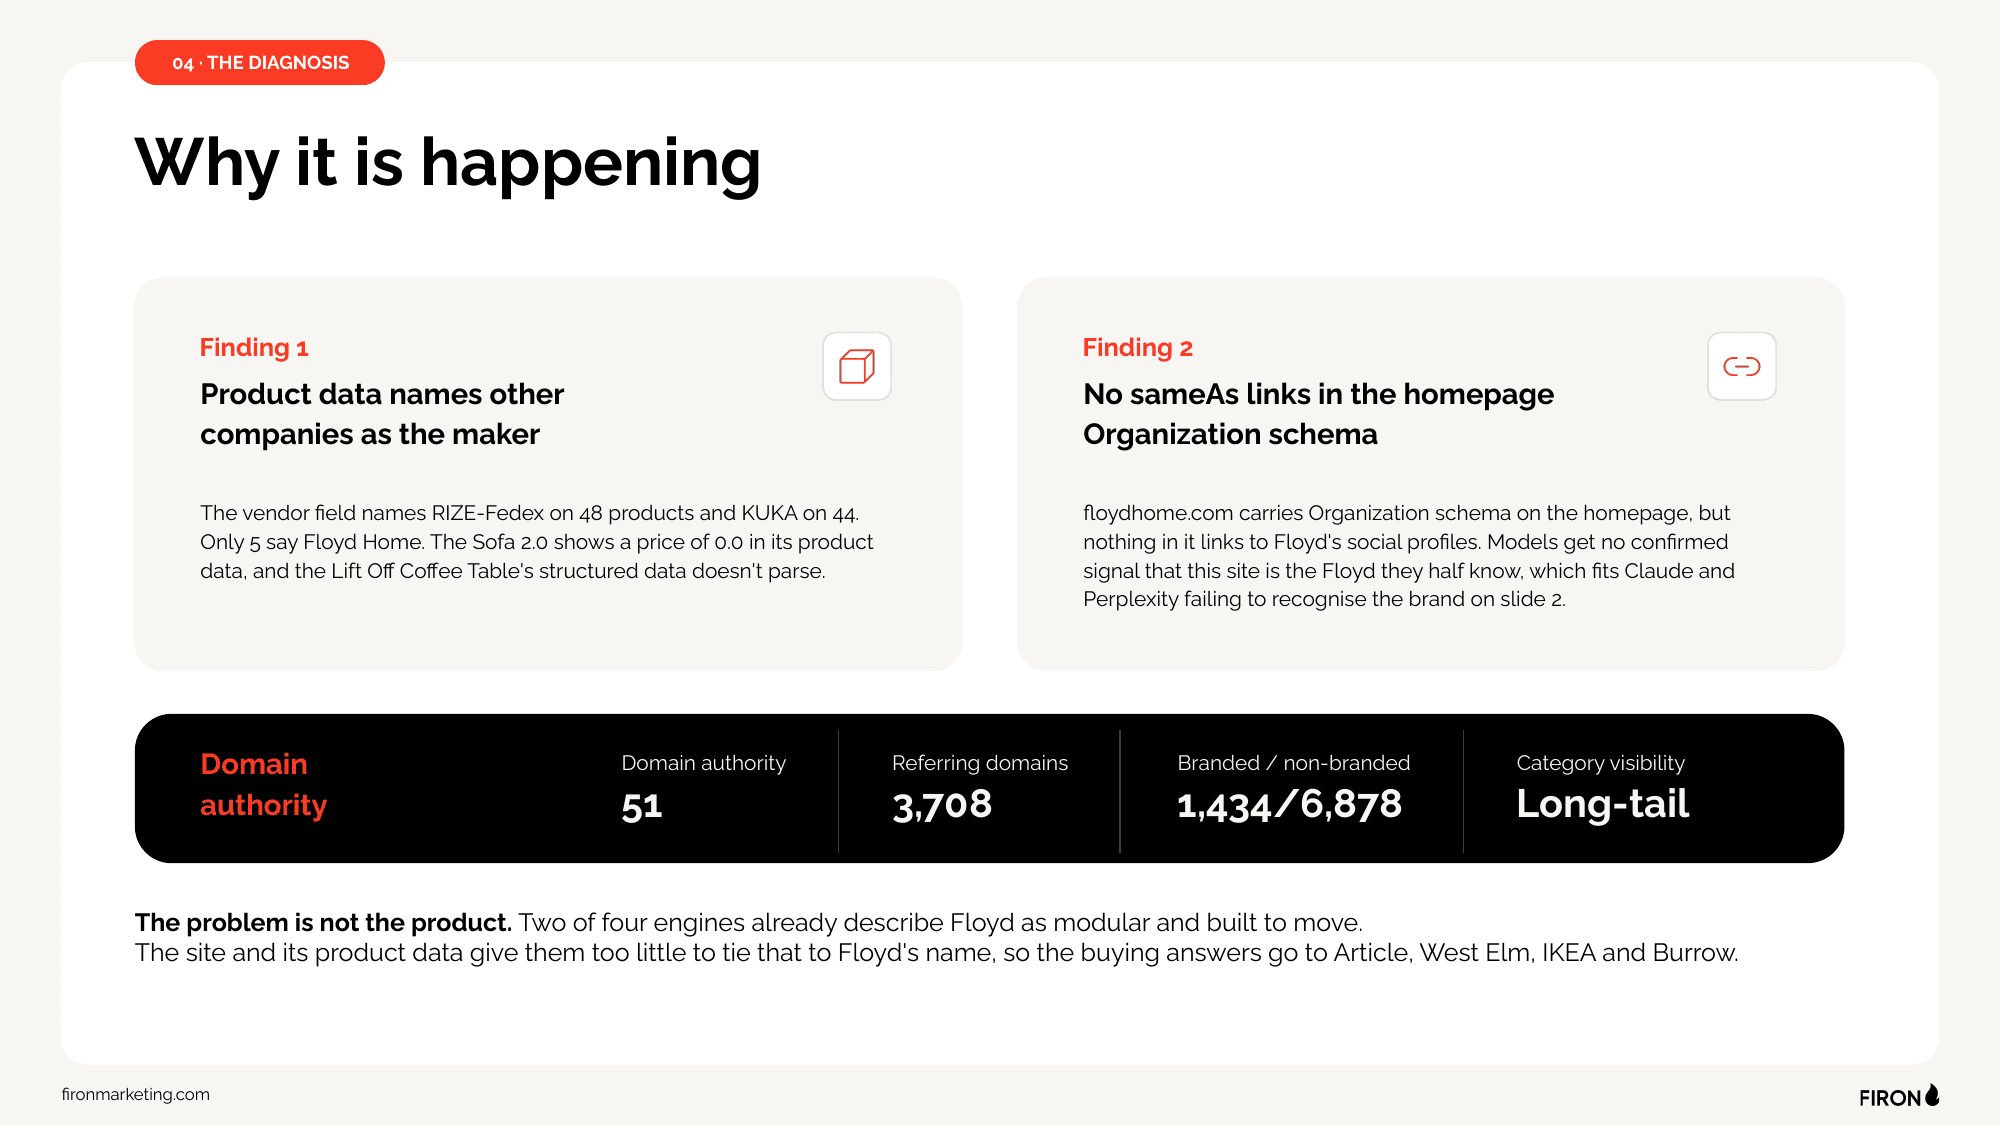
The diagnosis. One or two structural findings from the AI Readiness Audit, paired with your index and ranking data. Not a full audit. Enough to show the gap has a cause rather than being bad luck. Floyd had two.
The first is that the product data names other companies as the maker. The vendor field says RIZE-Fedex on 48 products and KUKA on 44, and only 5 say Floyd Home. The Sofa 2.0 shows a price of 0.0 in its product data, and the structured data on the Lift Off Coffee Table doesn't parse. This is the agentic feed readiness check, which tests whether a shopping agent can read the product catalogue. It shows why a machine cannot pick you.
The second is that the homepage Organization schema has no sameAs links. A missing sameAs declaration is not a cosmetic issue when the model cannot resolve which company with your name it is describing. Floyd's models get no confirmed signal that this site is the Floyd they half know, which fits Claude and Perplexity failing to recognise the brand.
Floyd's index data sits beside the findings: domain authority 51, 3,708 referring domains, 1,434 branded against 6,878 non-branded, and long-tail category visibility. The problem is not the product. Two of four engines already describe Floyd as modular and built to move, but the site and its product data give them too little to tie that to Floyd's name, so the buying answers go to Article, West Elm, IKEA and Burrow.
The three fixes. Specific to you, named page by named page, each one tied to the finding it comes from. Given away with no strings. Floyd's three:
Put Floyd Home in the vendor field across the catalogue, fix the 0.0 price on the Sofa 2.0 page and repair the structured data on the Lift Off Coffee Table page. This addresses finding 1 on slide 4.
Add sameAs links from the homepage Organization schema to Floyd's social profiles. This addresses finding 2 on slide 4.
Build one buyer page, furniture for people who move, answering the buying questions where Floyd ranks fifth: which modular furniture to buy if you move often, how it assembles, what it costs. This addresses slide 2.

Why can a prospect not produce this themselves?
Mostly because of the diagnosis.
A founder with a ChatGPT subscription can get a blurry version of the first three sections. They will get one engine rather than four, they will get it while logged into an account that already knows what they have been researching, and they will be scoring the answer to a question they framed themselves. That is not nothing, but it is an opinion, not a measurement.
The diagnosis is different. The readiness pass gives crawl permissions, JavaScript rendering, schema completeness, entity consistency and content structure. It deliberately carries no index data, no domain authority, no referring domain count, no branded and non-branded split. That data comes from elsewhere in our stack, and we would rather say so than imply one tool does everything. The two halves together are a diagnosis. Either half alone is a symptom list.
Request the AI Perception Report on your brand and we will run it before we speak.
What is automated, and what is judgment?
A report like this takes about twenty minutes of our time. Most of it is tool output. The leaderboard, the perception scores and the list of what the models get wrong all come straight from the engines and our own scoring. That part is repeatable and it is not where the value sits.
Three things in the report are judgment, and those three are what make it worth reading.
Choosing the three competitors is the most consequential decision in the whole report. A leaderboard built against the wrong three reads as generic and tells you nothing you did not already assume. Writing the target answer is positioning work, not tool output: it should be the best true sentence about your business, with the model's errors corrected inside it. Picking the three fixes is expertise, and it is the part we give away.
What does the report not include?
It is a diagnostic, not an audit. It does not include a full technical crawl, a keyword strategy, a content plan, or a competitive backlink analysis. The diagnosis shows one or two findings, not the list of everything wrong with your site. The purchase-intent line and the feed readiness check are free diagnostics, not line items.
It also reads mostly what the models learned in training rather than the live web (Gemini can't turn web search off), so if you shipped changes last month, this report will not reflect them yet. And it is a snapshot. Models update, and the scores move.
Finally, it does not tell you whether your revenue problem is an AI visibility problem. It tells you what the engines say about you, and why. What that is worth to your business is a conversation, which is the point of the call.
Why we hand over the fixes
A prospect who takes the three fixes, implements them alone and never speaks to us again is a fine outcome. Most will not. The ones who do come back.
Holding the fixes back to force a second call is what every other agency does with a free audit, and it is why nobody believes a free audit is free.
Getting one
Book a call. We run the report on your brand before we speak, and we walk you through it on the call. You keep it either way.
The nine tools behind it, and the method they sit in, are set out on the tools pillar.
Frequently Asked Questions
Is the AI Perception Report really free?
Yes, including the three fixes at the end. There is no gated second version and no paid upgrade of the same document. The report exists because the fastest way to show what we do is to do a small piece of it on your brand. You keep the report whether or not we work together, and you are free to hand the fixes to your own developers.
How is this different from asking ChatGPT about my own brand?
Three ways. We query four engines rather than one, we use fresh sessions with no history so your own research does not shape the answer, and we run them with web search off (Gemini can't turn it off) so you mostly see what the model knows rather than what it can look up. We also pair that with crawl and index data, which is what turns a strange answer into an explained one.
What do you need from me before the call?
Your domain and the three competitors you think you are up against, though we may pick different ones and tell you why. Nothing else. We do not need access to your analytics, your content management system or your search console to produce the report.
How current is the data in the report?
The perception data reflects what the models learned in training, so recent site changes will not appear yet. The crawl data is taken the day we run the report. We date every report for that reason, and the scores will move as the models update.
Firon Marketing is a strategic consultancy. All technical implementations should be reviewed by your engineering team to ensure compatibility with your specific tech stack.
Alexander Jordan
Founder, Firon Marketing
15+ years scaling brands. A strategic partner for high-growth founders, focused on sustainable revenue models and long-term equity value.


